Year 2 individual coursework · Data Science for Applied AI
Comparing classical classifiers, carefully
An individual study comparing four classifier families on the Wisconsin breast-cancer dataset. The useful result is not a winner but the relationship between preprocessing, data boundaries and the kinds of error each model makes. A benchmark exercise, not a clinical tool.
- Context
- Individual coursework · Data Science for Applied AI, University of Bradford
- My role
- Sole author: analysis, preprocessing, modelling, evaluation and report
- Dates
- January 2025
- Status
- Completed academic study · notebook and report on GitHub
Stack
- Python
- pandas
- NumPy
- scikit-learn
- matplotlib
- seaborn
The short version
Each point is expanded, with diagrams, in the sections below.
- 01Problem and constraints
- How do linear, margin-based, tree-based and neighbour-based models compare on a small tabular dataset, without mistaking noise for a winner?
- 02My responsibility
- Individual work: every step from exploration to the report.
- 03The design
- One fixed random split, scaling fitted on training rows only, four baselines, then errors compared class by class.
- 04What I implemented
- Exploratory analysis, preprocessing, four baseline models, grid searches, confusion matrices and ROC analysis.
- 05The team’s part
- None: individual coursework.
- 06What was delivered
- A notebook and a written report, both now public on GitHub.
- 07What testing established
- Baseline test accuracy ranged from 94.7% to 97.4% on 114 rows: differences of one to three cases.
- 08Learned, and unfinished
- Keep preprocessing inside cross-validation, stratify, hold a test set back, and report the error that matters. A later review found the tuning experiments mixed two versions of the data.
On this page
The question
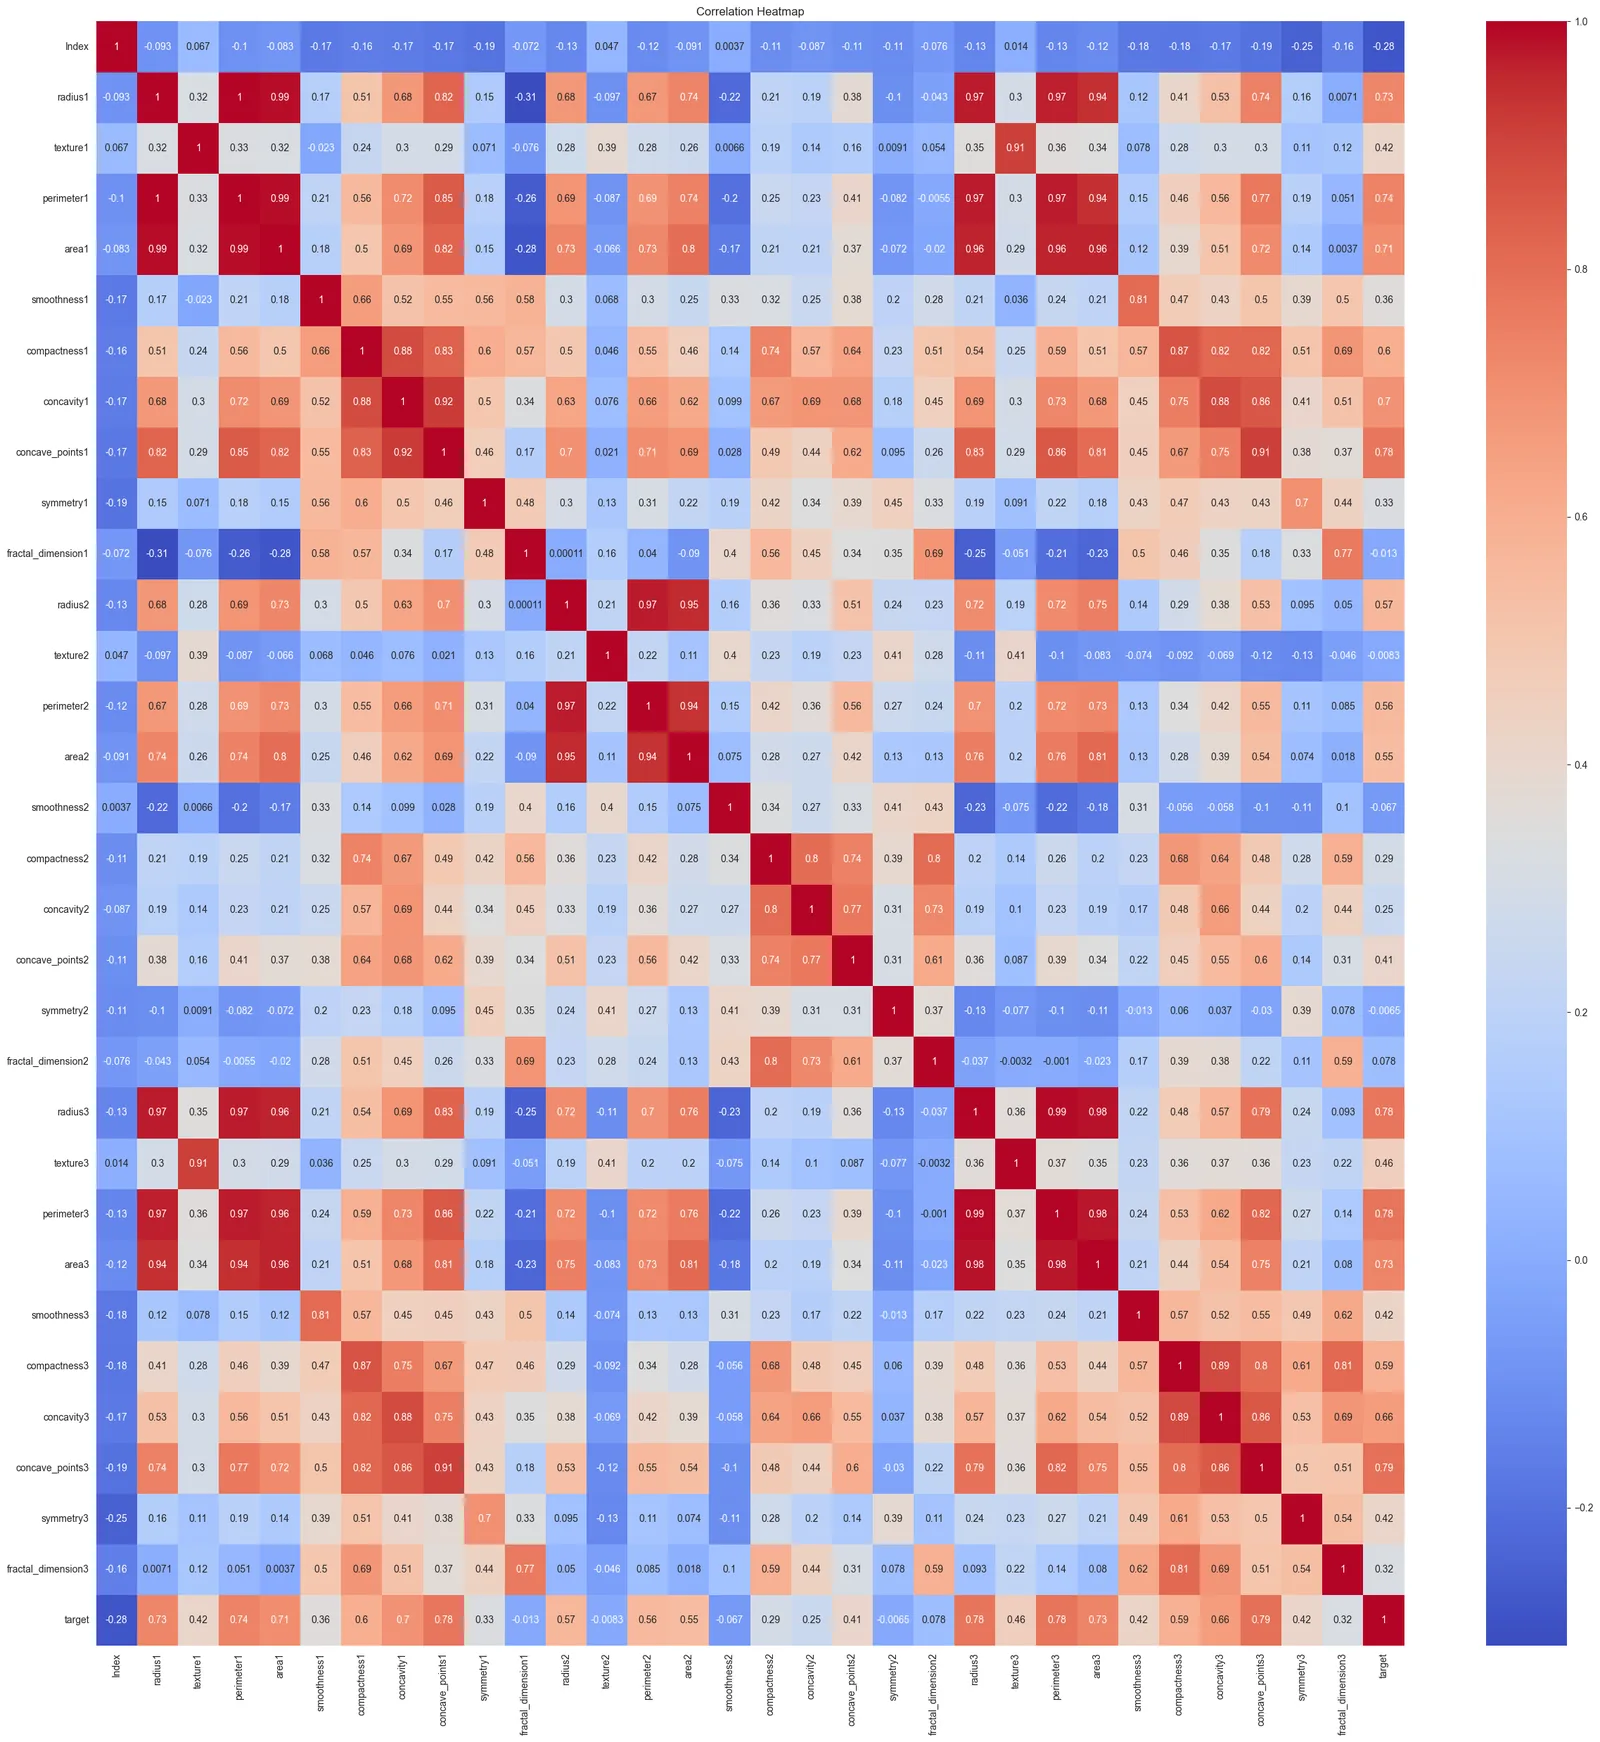
Each model family makes different assumptions about the same 30 measurements. I wanted to see how those assumptions played out on a small dataset, and how much of any difference was really just a few test cases.
The experiment
The baseline comparison lives in one notebook cell: load the data, split it once with a fixed seed, fit the scaler on the training rows only, then fit and score all four models. Everything else in the notebook, including outlier removal, projections and grid searches, ran as separate experiments and is kept apart from the baseline results.
The baseline experiment, and what sits outside it
- Implemented
- Stored data
- Incomplete, or a gap found in testing
Text version of this diagram
Parts
- Baseline comparison (one notebook cell)
- Load the dataset — 569 tumours, 30 numeric features, benign / malignant
- Random 80/20 split — seed 42; not stratified
- Training rows: 455
- Test rows: 114 — 43 malignant, 71 benign
- Fit StandardScaler on training rows — then transform the test rows
- Fit four baselines — logistic regression, linear SVM, random forest, k-NN
- Train vs test accuracy + confusion matrices
- Separate experiments: not part of the baseline
- Exploratory analysis — distributions, correlations, class balance
- Outlier removal on a UCI copy — 569 → 486 rows, before any split; incomplete or failed in testing
- PCA and t-SNE views — unscaled features
- Grid searches — 3–5 folds; scaler fitted before CV; mixed datasets; incomplete or failed in testing
Connections
- Load the dataset → Random 80/20 split
- Random 80/20 split → Training rows: 455
- Random 80/20 split → Test rows: 114
- Training rows: 455 → Fit StandardScaler on training rows: fit
- Test rows: 114 → Fit StandardScaler on training rows: transform only
- Fit StandardScaler on training rows → Fit four baselines
- Fit four baselines → Train vs test accuracy + confusion matrices
- Exploratory analysis → Outlier removal on a UCI copy
- Outlier removal on a UCI copy → PCA and t-SNE views
- Outlier removal on a UCI copy → Grid searches
What the results show
Four baselines on one fixed split: close scores, different errors
| Model | 93%95%97%99% |
|---|---|
| Logistic regression | 97.37%training 98.68%, test 97.37% |
| Random forest | 96.49%training 100%, test 96.49% |
| Linear SVM | 95.61%training 98.68%, test 95.61% |
| k-NN (k = 5) | 94.74%training 98.02%, test 94.74% |
| pred. M | pred. B | |
|---|---|---|
| true M | 41 | 2 |
| true B | 1 | 70 |
| pred. M | pred. B | |
|---|---|---|
| true M | 40 | 3 |
| true B | 1 | 70 |
| pred. M | pred. B | |
|---|---|---|
| true M | 41 | 2 |
| true B | 3 | 68 |
| pred. M | pred. B | |
|---|---|---|
| true M | 40 | 3 |
| true B | 3 | 68 |
- training accuracy
- test accuracy
The random forest fits every training row yet misses three malignant cases on the holdout; logistic regression and the linear SVM each miss two. Reading the errors, not just accuracy, is what makes the comparison useful.
Compare model families, not just scores
Holding the split fixed made the comparison about the models' assumptions. The random forest fitted every training row but was not the best on the holdout.
Read the errors
A missed malignant case and a false alarm have very different costs. Confusion matrices showed which models made which mistake.
What I would tighten now
- Put scaling inside a scikit-learn Pipeline so each cross-validation fold fits its own transform; some searches scaled first.
- Keep one dataset: some tuning ran on an outlier-filtered copy (486 rows), so the tuned and baseline results are not comparable.
- Stratify the split and keep an untouched final test set instead of reusing the same 114 rows.
- Report malignant recall directly: the notebook's precision and recall treated benign as the positive class.